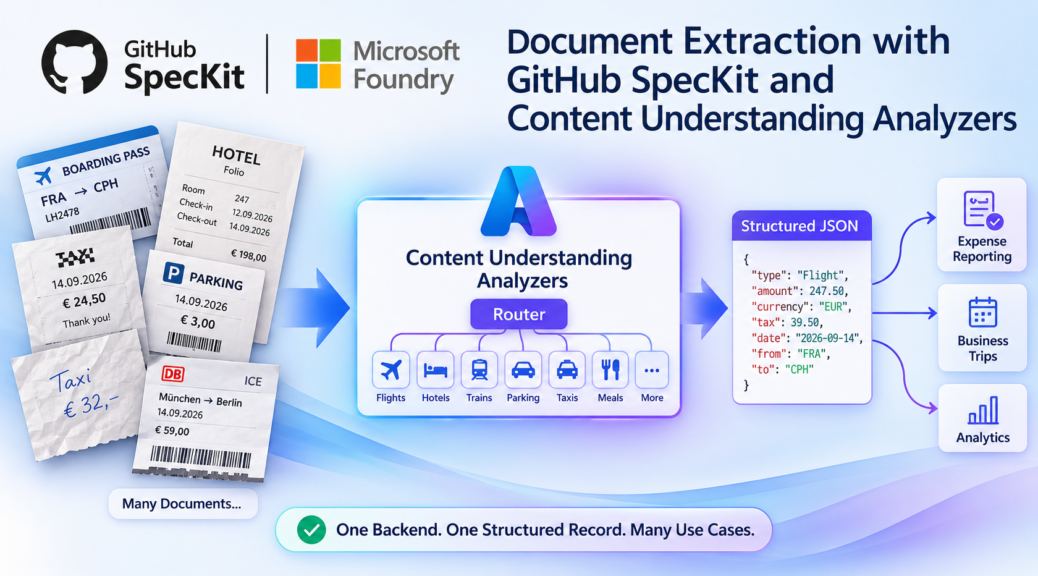
Document Extraction with GitHub SpecKit and Content Understanding Analyzers
My expense documents are usually airline receipts, hotel folios, parking tickets, a handwritten taxi slip. Some are PDFs, some are phone photos, and they come in German, English, Danish, Polish, or wherever I received them. Now imagine one backend that reads all of them and returns the same clean expense record every time. That is exactly what Content Understanding analyzers in Microsoft Foundry can do. And this time, I did not code them from scratch. Look at the picture. Documents…